 kengdevLet’s talk
Updated on 2026-09-10
Human in the loop describes an architecture where a person validates, corrects or rejects the output of an automated system before it has any effect. The checkpoint sits where an error is expensive: a message sent to a client, an accounting entry, a decision that commits the company.
Place validation points where they earn their cost, without turning the agent into a form nobody reads anymore.
A blanket check on everything always ends up clicked through without being read. Target the cases where an error is expensive.
HITL: supervision, not build
Human in the loop is about deciding where humans stay in the loop of an automated system. The build side (the flow, the tools, the business KPIs) is covered in how to create an AI agent. Here, we talk about validation queues, thresholds, mental load and capture.
Three intents often mix: safety (blocking a dangerous action), quality before a customer send, and learning (producing labels to improve the system). If you do not separate them, you end up over-validating everything or letting the risk through.
Set autonomy by action type: suggestion, draft for approval or execution within a defined scope. The acceptable level depends on observed errors and their consequences. There is no universal target percentage of autonomy.
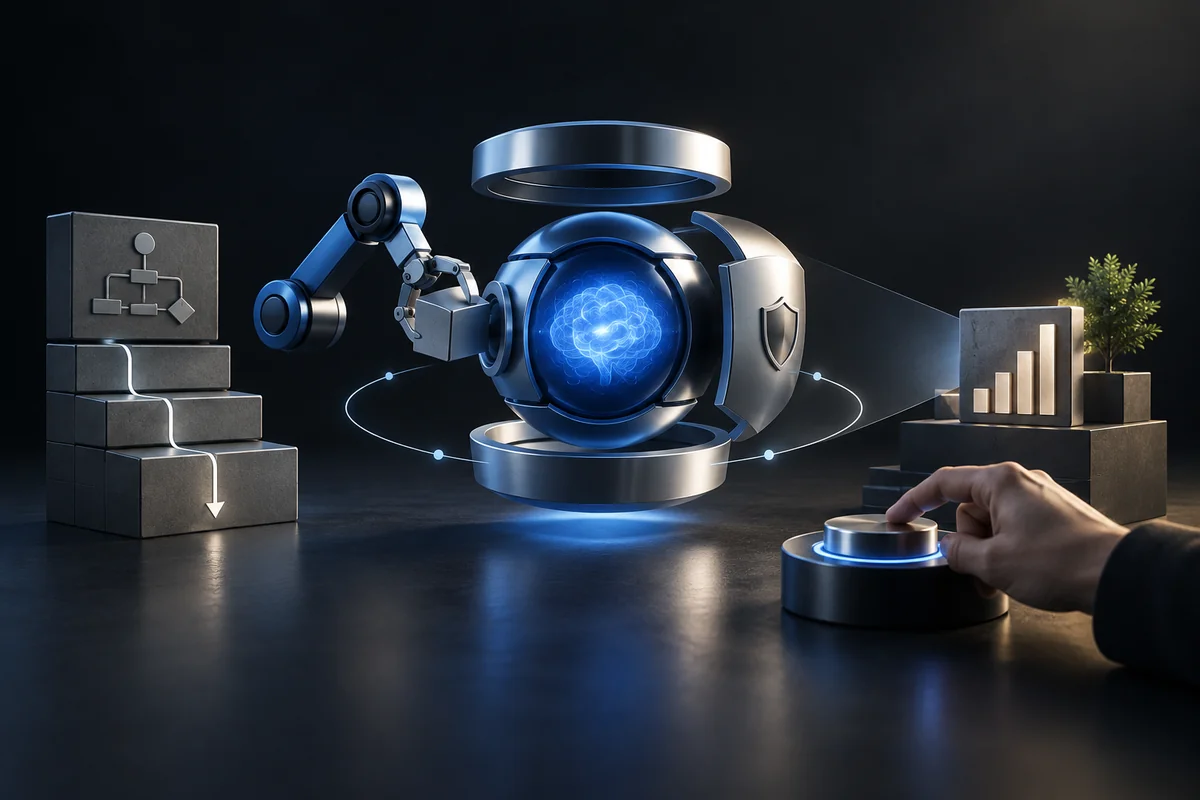
Without the third brick (control), you just have a POC / a demo.
Where to place humans in the flow
Place HITL where the error cost multiplied by its probability peaks. A standard follow-up email carries a low risk. A price change, a legal send or a VIP client carries a high one.
Then map each action to its supervision level:
| Action | Supervision |
|---|---|
| Read | Often automatic |
| Write a draft | Often automatic |
| Send | HITL at first |
| Write to the CRM | HITL, then automatic on green cases |
| Delete, pay, sign | Permanent HITL, or forbidden |
Review fatigue can lead people to approve without reading. Automate only cases with acceptable risk, and keep mandatory approval for sensitive actions. The review queue should show changes, sources and the reason for escalation.
The same logic holds for code: AI review speeds up the first pass, and humans keep ownership on auth and payments (see AI code review).
Thresholds and business policies
A model confidence score is not enough. Combine it with deterministic rules: an amount above a threshold, a VIP client, an uncovered language, a missing document, detected PII, a tool outside the allowlist.
Calibrate those thresholds on an annotated sample of 50 to 200 cases, measuring precision and recall of the green class. Too low a threshold floods the queue; too high a threshold lets errors through. Recalibrate after every prompt or model change.
Write the policy in plain language, readable outside engineering: "The agent may auto-send J+7 follow-ups if the quote is under €5k and the client is not VIP. Otherwise, sales validation."
Version that policy like code, with the date, the author, the reason and the impacted metric.
Capitalize on validations
Every accept, edit or reject is useful data. Store the input, the agent output, the human action, the comment and the review time.
That log then serves four purposes:
- Feeding corrected few-shot examples
- Identifying recurring error classes
- Spotting autonomy candidates, those cases always accepted without edits
- Training the validators
On the GDPR side, minimize PII in the logs, set a retention period and restrict access. HITL does not excuse an ungoverned data lake.
Ship HITL in 30 days
The rollout fits in four weeks:
- Map the actions and classify the risks
- Ship a minimal validation UI and the logs
- Calibrate the thresholds on a real corpus
- Track the metrics and expand the green cases a first time
Three roles are enough: a business owner for the rules, a tech owner for the tools and logs, and validators trained with a short checklist.
HITL health shows in the median review time, the share of green cases, the share of edits, post-action incidents and mental load. If the load explodes, shrink the automatic scope.
If you want clean HITL on a real process, we can scope it in 20-40 minutes.
Frequently asked questions
HITL vs human on the loop?
A human in the loop validates unit cases, like a send. A human on the loop supervises thresholds and incidents without validating every ticket. Both coexist in a mature production.
Does HITL kill ROI?
Poorly designed, yes: 100% review creates a queue. Well designed, it keeps simple volume automatic, puts humans on the risk and strengthens adoption.
Need an LLM confidence score?
A confidence score is useful as a complement, but insufficient alone. Prefer the combination of a score, business rules and an error history.
Who validates: business or eng?
The business side validates the substance. Engineering validates the system: the tools, the logs and the regressions.
Link to AI code review?
The logic is the same: the AI comments, and humans approve on critical paths.
GDPR?
The HITL log is a data processing activity in its own right: it needs a legal basis, minimization, a defined retention and access control.
Sources and references
- AI Risk Management Framework (AI RMF 1.0)NIST
The reference framework for identifying where a control is justified. Deliberately sector-agnostic, so it transposes.
- Règlement (UE) 2024/1689 sur l'intelligence artificielle, article 14EUR-Lex
The official text. Article 14 states what human oversight must concretely allow on a high-risk system.
- Intelligence artificielle: les recommandations de la CNILCNIL
The French GDPR angle: legal basis, informing the people concerned, and the case of fully automated decisions.