 kengdevLet’s talk
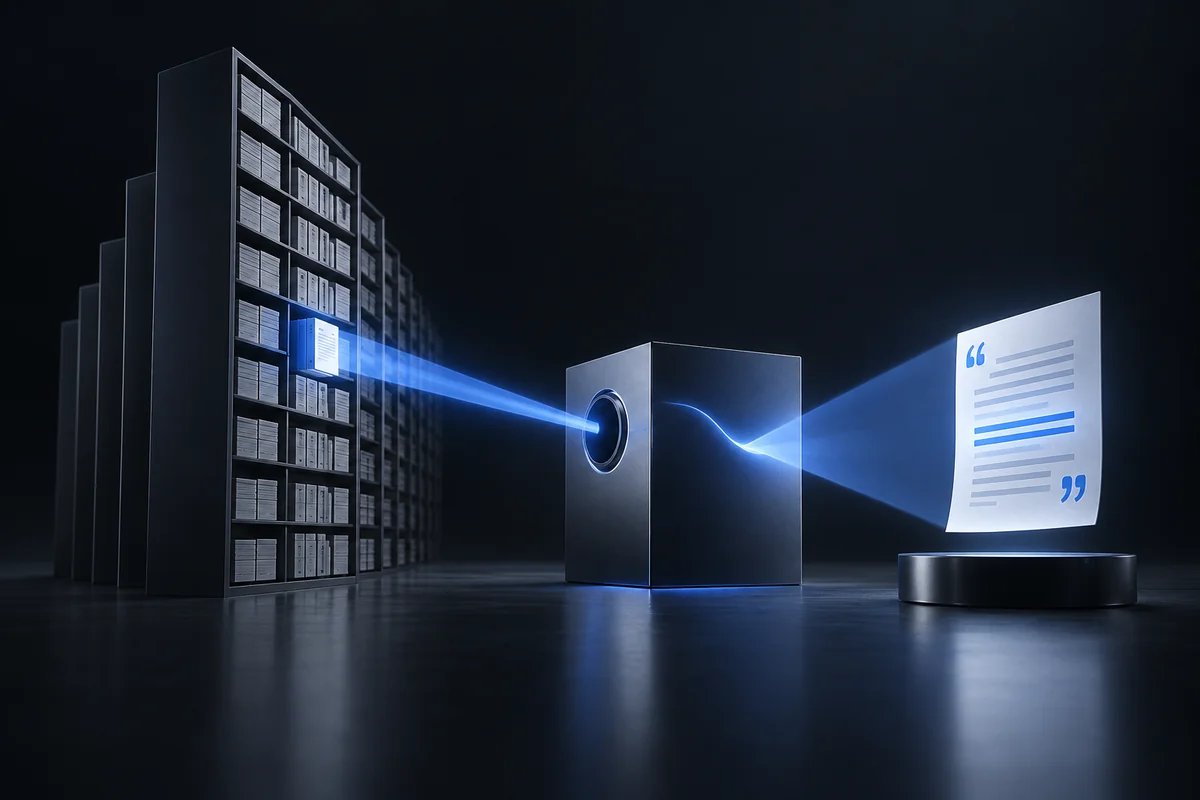
RAG and fine-tuning answer two different questions. A RAG fetches up-to-date facts at the moment the question is asked, without touching the model. Fine-tuning, by contrast, changes its behaviour for good: you show it examples, and they end up in the weights or in an adapter.
Choose between them on verifiable criteria, or decide with open eyes to combine them.
If the problem is knowledge, use a RAG. If it is format or tone, fine-tuning earns its place.
RAG vs fine-tuning: two levers, two jobs
The two approaches play different roles. A RAG fetches fresh facts at the moment the question is asked, without touching the model. Fine-tuning, on the other hand, changes the model's behavior for good: you show it examples, and they end up in the weights or in an adapter.
So the right reflex is to start from your measured failure, not from the hypest tech. The typical failure is a model that doesn't know your catalog. In that case, start with a RAG, or even a plain search. If the model knows the facts but returns the wrong format or tone, then fine-tuning, or simply well-built prompts and skills, can win.
Many teams launch a fine-tune to paper over a messy corpus. It costs a lot, and the result goes stale the next time prices or procedures change.
Decision grid in 6 questions
Before choosing between RAG and fine-tuning, run your case through this grid. Each question points to a different lever depending on your answer.
| Question | If yes | If no |
|---|---|---|
| 1. Do the facts change every week? | RAG or a live base, not a monthly retrain | Fine-tuning stays on the table |
| 2. Do you have clean example data, and the rights to use it? | A fine-tune becomes possible | RAG + prompts |
| 3. Is the risk legal or customer-facing? | Retrieval + citations + human review first | More room to experiment |
| 4. Is the need about style, domain language or ticket format? | Skills and prompts, maybe a light fine-tune | It is a knowledge problem: RAG |
| 5. Can you serve a custom model (ops budget)? | Fine-tuning stays an option | API + RAG |
| 6. Do you have an eval set? | You can compare both options | Neither option is validated |
Then count the answers. If three or more push toward documents and freshness, start with a RAG. If your corpus is already spotless and the failure is purely behavioral, look at fine-tuning.
Patterns that work together
In practice, the two levers combine well. The RAG handles the facts, the system prompt and skills carry the process. A fine-tune, or a simple adapter, only steps in on the output format, once retrieval is stable. On an agent, the split is the same: deterministic tools for computation, a RAG for the docs, human review before anything is sent.
What you want to avoid is the dual system nobody governs: an opaque fine-tune on one side, a never-evaluated RAG on the other. One measurable pipeline beats two hacks.
If you run locally on open-weights models, local fine-tuning is possible but heavy. There too, the first lever is almost always a RAG over your internal corpus (see local AI and the open-weights news).
Classic traps
The same mistakes come back in most projects:
- Fine-tuning on FAQs that are no longer up to date
- Measuring success on demo vibes instead of an eval
- Ignoring access rights (ACLs) in retrieval
- Believing a fine-tune removes the need for citations
- Changing the model and the corpus on the same day, without a baseline
The countermeasure fits in one sentence: freeze a baseline, change one variable at a time, keep an experiment log, and name one owner for the data and another for the model.
One-page decision (template)
To settle the decision cleanly, one page is enough. It contains:
- The context and the measured failure
- The three options: RAG, fine-tune, prompts and skills only
- The 90-day cost and the risk of each option
- The eval protocol, the go / no-go decision and the review date
If the go lands on RAG, continue with the RAG LLM guide. If it lands on fine-tuning, require a non-regression eval and a retrain plan. And if both are justified, sequence them: RAG first.
If you want to settle RAG vs fine-tuning on a real case, we can scope the decision together in 20-40 minutes.
Frequently asked questions
RAG or fine-tuning: which first?
For most SMEs, RAG (or plain search with a good prompt) comes first. Fine-tuning comes in when the remaining failure is behavioral and your example data is clean.
Does fine-tuning replace RAG?
It rarely does once the facts keep moving: model weights do not make a real-time document store.
Can we combine both?
Yes, and it is even the most common pattern: the RAG carries the substance, the fine-tune (or an adapter) carries the format. Keep a single eval system for both.
How many examples for a useful fine-tune?
It depends on the task, but quality beats quantity. A few hundred clean examples beat thousands of noisy rows. Validate with an eval, not raw volume.
What about prompt engineering?
It is always the first layer to try. Many "we must fine-tune" cases get solved with clear specs, skills and versioned few-shot examples.
Link to context engineering?
Context engineering decides what goes into the model's window, RAG results included. Fine-tuning decides what the model keeps in its weights. The two are complementary.